
Picture a developer shipping a signup form on a Friday afternoon. By Monday, the sales team has a pile of new leads, and plenty of them have no email address. The form worked fine. Nobody decided early on what the data was for, how it should arrive, or who’d clean it up. Sound familiar? Most data problems start long before the database. They start the moment you choose how information comes into your system.
What Is a Data Collection Method?
It’s the structured way you gather information from people, systems, or devices so you can analyze it later. Surveys, interviews, server logs, and APIs (the connections that let one app request data from another) are all examples. The right fit depends on your goal and budget.
Primary and Secondary Data: Where Your Data Starts
Primary data is information you collect yourself, for your own question, like a customer survey or event tracking, which logs what users do in your app. Whatever the source, your method of collecting data decides how far you can trust the results. Secondary data is information someone else already gathered, such as a public dataset or a vendor’s report. Primary data costs more time but fits your needs; secondary is faster, though you’re trusting someone else’s choices.
Most real projects mix both. A team using a CRM (the software that stores customer records and conversations) might pair its own form submissions with purchased company data like industry and headcount. Do the two sources even agree?
Methods and Techniques of Data Collection You’ll Actually Use
Surveys and forms
Ask people directly. Surveys and signup forms are cheap and fast, and they scale well. The catch is self-reported data, which can be incomplete or just plain wrong. Keep forms short and check fields as people type.
Interviews and observation
Interviews give you the “why” behind a number. Watching someone use your product shows you what they’d never think to mention. Both take time, so they’re best for small, high-value questions.
APIs and logs
Automated data collection methods pull records from APIs and server logs (the files where systems record what happened) without anyone filling out a form. They’re consistent and fast, but they only capture what you thought to track.
Analytics and existing records
Web analytics tools track visits, clicks, and the points where visitors give up. Your own CRM exports, support tickets, and past orders are another rich source, and they’re already sitting there. Ever checked what you already have before building something new?
Quantitative vs. Qualitative Data Collection Methods
Quantitative data is anything you can count or measure, like signups per day or load time. Qualitative data is descriptive, like interview notes or open-ended survey answers. Numbers tell you what happened. Words tell you why.
Say signups dipped last week. A dashboard shows the dip, and a few customer calls explain it. Quantitative methods suit dashboards and comparisons; qualitative ones suit new problems you can’t yet define. Neither is better; they answer different questions, and most projects need both. Choosing the right method of collecting data starts with your question, not your tool.
How to Choose the Right Approach
Start with three questions. What decision will this data support? Who’s the source, and will they tell you the truth? How much time and money can you spend? Then match the method. A short survey suits a quick pulse check. Interviews suit messy problems. APIs and logs suit anything you need continuously. If privacy rules apply to your users, check consent requirements before you collect a single record.
Common Myths About Data Collection Methods
A few beliefs trip teams up again and again.
- Myth: More data is always better. Extra fields add noise, storage costs, and privacy risk. Collect what you’ll use.
- Myth: Surveys are outdated. They’re still useful when the question is clear and the wording is neutral.
- Myth: Automated collection means accurate data. Tracking can break quietly, and nobody notices until a report looks odd.
- Myth: You can fix it later. Cleanup is possible, but it usually costs far more than collecting it properly.
Keep Your Data Clean After Collection
Data collection methods only get you halfway, because the rest is keeping records usable. If you work with customer records, our guide to CRM data quality explains how duplicates and missing fields creep in.
Every record also carries context, like when it arrived and from where. That’s metadata (data about your data), and this explainer on what is metadata shows why it matters.
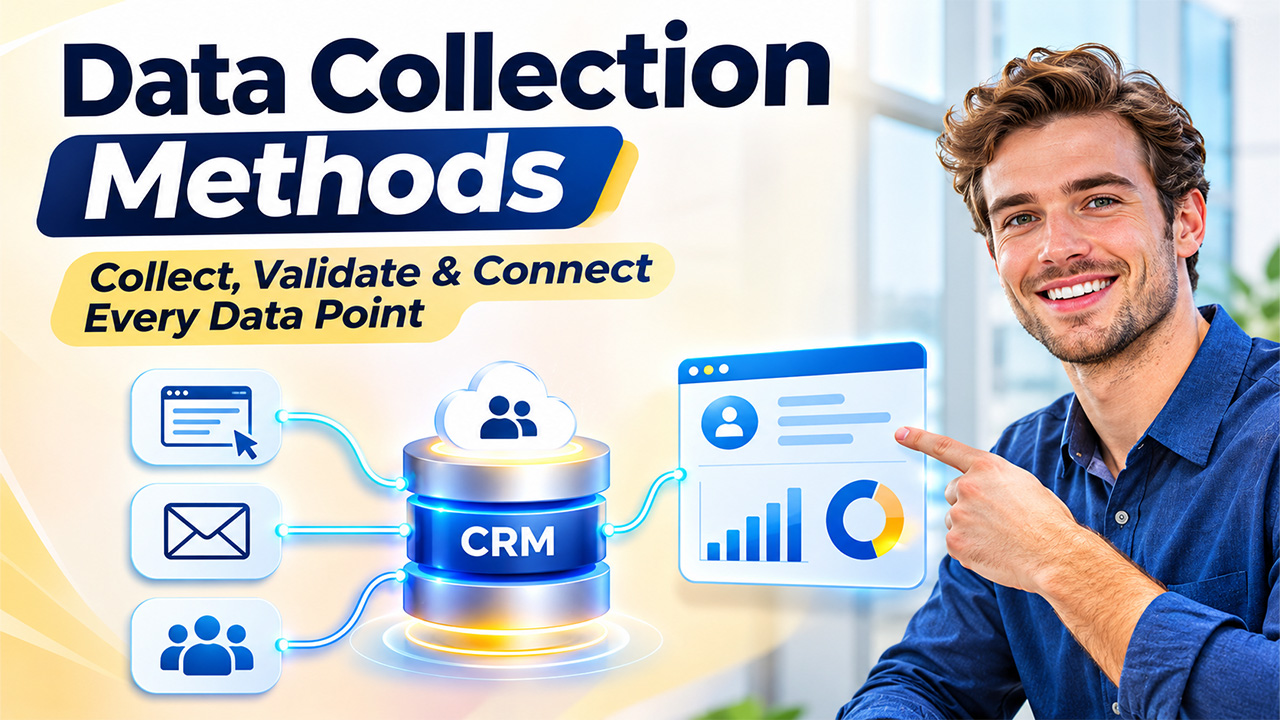
Then decide where it all lands. This breakdown of a CRM database shows how records are stored and connected, so you can trace each one back to the method of collecting data that produced it.
A practical habit: log the source and date of every record at the moment it’s collected. Future you will thank present you, especially when a number looks off and you need to know where it came from. And if you inherit a messy dataset, ask how it was collected before you ask how to fix it.
Where to Go From Here
Here’s the short version: there’s no single approach that fits every project, and that’s fine. The most dependable data collection methods match your question, suit your source, and leave a trail you can check.
Ready to tighten up your process? Try these three steps this week:
- List every place data enters your system, from forms to APIs.
- Audit one dataset for duplicates and missing fields.
- Pick one weak spot and fix the collection step, not just the symptoms.
Start with step one today, and share what you find with your team so everyone collects data the same way.
Frequently asked questions
Common options include surveys, interviews, observation, existing records, and automated sources like APIs and logs. Most teams combine a few, since each one covers different gaps. Your goal and your audience should drive the final mix.
There’s no single best way. Ask for only what you need, explain why you need it, and use a source that matches the question. Then test the process before you scale it, and document the choice so others can repeat it.
It depends on the job. Forms and in-app events work well for capturing new contacts, while interviews help when you need context behind the numbers. Whatever you choose, check that each field maps cleanly into your records.
Yes, and many teams do. Pairing numbers from analytics with a few customer interviews often gives a clearer picture than either alone. Just keep track of which source each record came from.
They set the ceiling for quality. Biased survey wording, unchecked form fields, or broken tracking can all show up later as unreliable records. Clean up the source and the downstream work gets lighter.